 A proxy-tuned learning rate makes the 8x wider model diverge
 ScalingMultiple choiceHardFree
 One neuron fires on citations, dialogue, HTTP requests and Korean textInterpretabilityMultiple choiceMediumPro
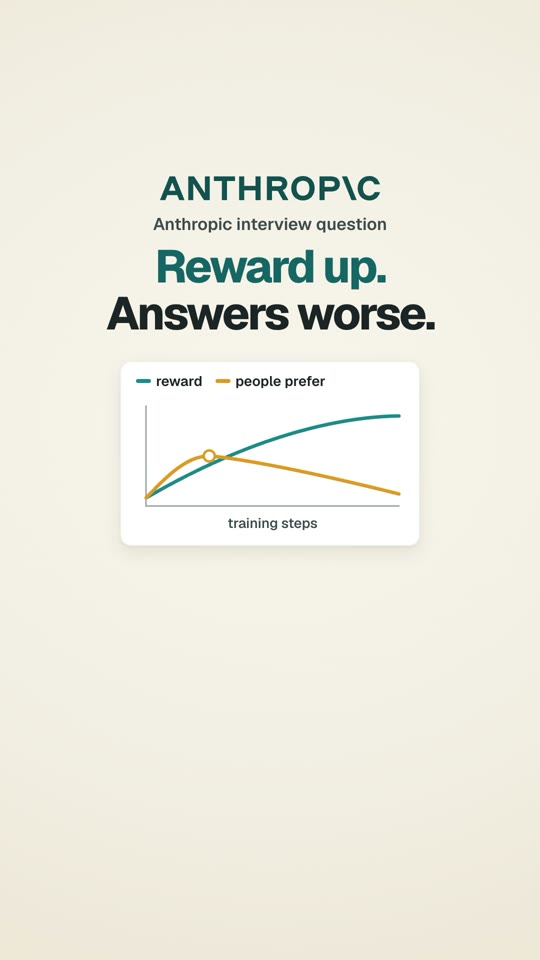 The reward keeps climbing, but people prefer an earlier checkpointRLHFMultiple choiceMediumPro
 Test accuracy sits under 10% for 24,000 steps, then climbs to 100%InterpretabilityMultiple choiceHardPro
 Your LLM judge flips its verdict when you swap the answers
 EvaluationMultiple choiceMediumFree
 After a learning-rate increase, loss spikes a few thousand steps inTraining stabilityMultiple choiceHardPro
 At a million tokens, one layer's activations don't fit on one GPUScalingMultiple choiceHardPro
 Ten hand-set weights add ten-digit numbers, but training needs 36ScalingMultiple choiceMediumPro
 57% on grade-school math, no more training, lots of inference compute
 ReasoningMultiple choiceMediumFree
 Your reward model picks right answers reached through wrong stepsReasoningMultiple choiceMediumPro
 More users, an idle GPU, and every user gets slowerInferenceMultiple choiceHardPro
 It knows who Daphne Barrington is, but can't say who directed her filmDataMultiple choiceEasyPro
 What forms inside a model at this bump in its loss curve?InterpretabilityMultiple choiceMediumPro
 The weights fit in INT8, but the activations don't
 QuantizationMultiple choiceHardPro
 Pretrained on 4K tokens, now it has to read 32KPositional encodingMultiple choiceMediumPro
 DPO loss keeps dropping, but by epoch 3 the answers degradeFine-tuningMultiple choiceHardPro
 You switch training to fp16 and the gradients round to zero
 Mistral AITraining stabilityMultiple choiceMediumFree
 Why does attention divide every score by the square root of d?Mistral AIAttentionMultiple choiceEasyPro
 The rule says 160B tokens for an 8B model. Llama 3 used 15 trillionMistral AIScalingMultiple choiceMediumPro
 RL on a 7B math model, and PPO wants a second 7B model as the critic
 RLVRMultiple choiceMediumPro
 100B tokens of text in your language, and compute for 4 trillionDataMultiple choiceMediumPro
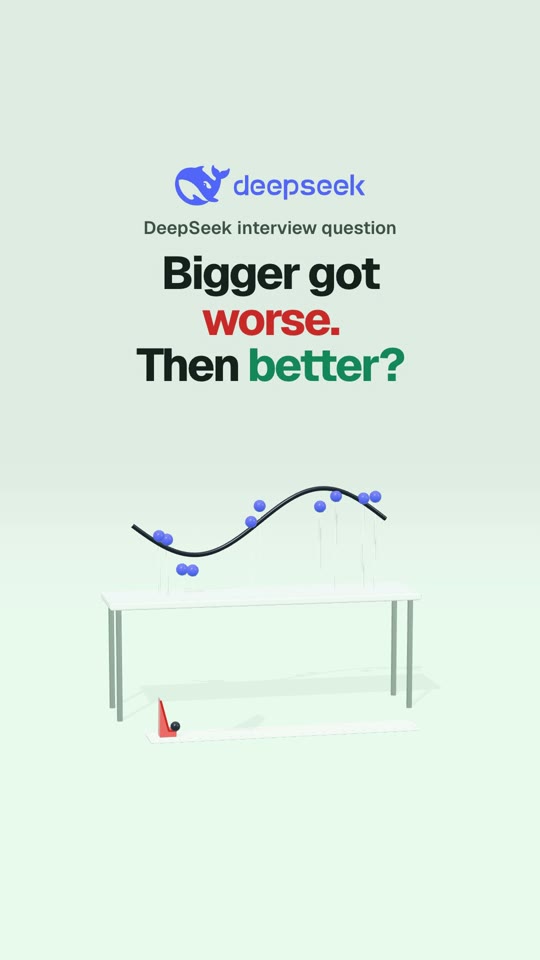 As the model grows, test error goes down, then up, then down againScalingMultiple choiceHardPro
 99% confident, but right only about 90% of the time
 EvaluationMultiple choiceEasyPro
 Why does a 47B model run about as fast as a 13B one?ArchitectureMultiple choiceEasyPro
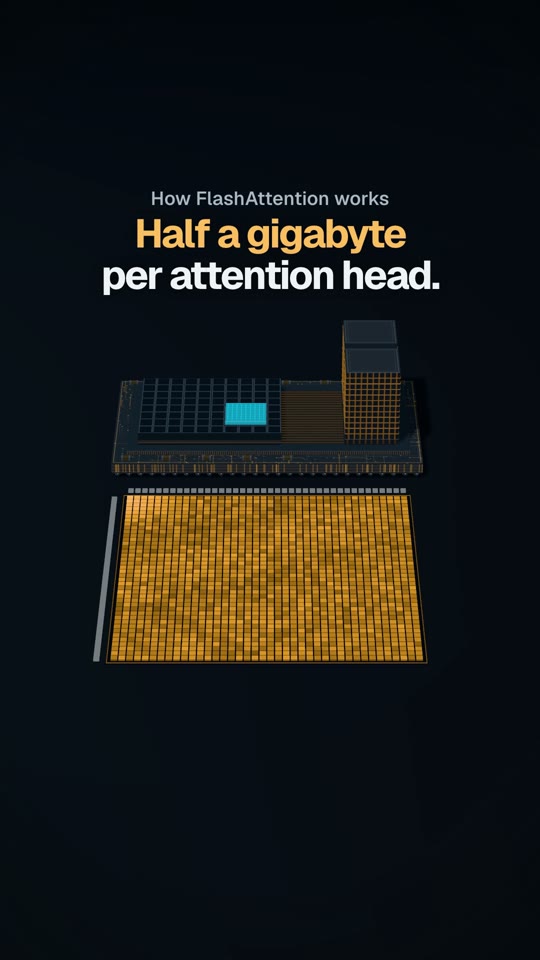 FlashAttention recomputes in the backward pass and still runs fasterConceptAttentionMultiple choiceMediumPro
 Why not let the draft model write twenty tokens at a time?ConceptInferenceMultiple choiceMediumPro
 Push the MoE load-balancing loss too high and the model gets worseConceptArchitectureMultiple choiceEasyPro
 A chatbot runs fine for an hour, then outputs gibberishConceptInferenceMultiple choiceMediumPro
 Aces 20-digit addition, fails at 100 digitsConceptPositional encodingMultiple choiceEasyPro
- Checking that an LLM judge's position bias is goneEvaluationShort answerMediumPro
- Testing that a 32K-context model really uses the far endPositional encodingShort answerMediumFree
- Turning step labels into one score for a whole solutionReasoningShort answerMediumPro
- Fitting more users at the same tokens per secondInferenceShort answerHardPro
- Checking that a sparse autoencoder feature means one thingInterpretabilityShort answerMediumPro
- Picking the draft length for speculative decodingConceptInferenceShort answerHardPro
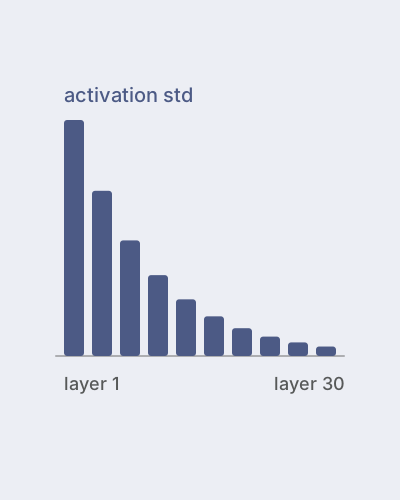 A 30-layer ReLU net with Glorot init never starts learningConceptInitializationMultiple choiceEasyPro
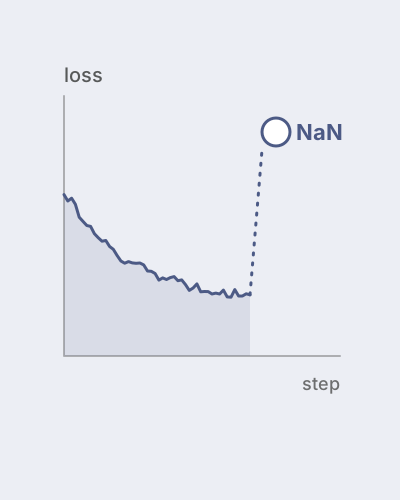 Cross-entropy turns NaN once a logit passes 89ConceptTraining stabilityMultiple choiceEasyPro
 Names and compounds keep coming out as UNKConceptTokenizationMultiple choiceEasyPro
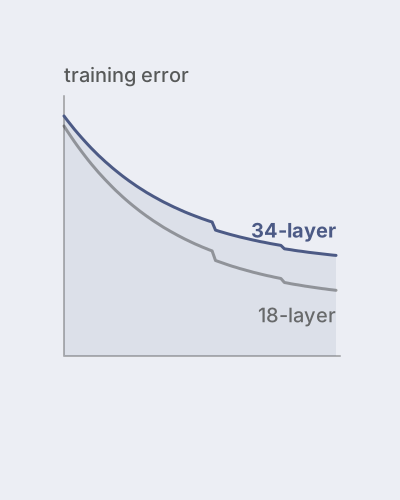 The 34-layer net has higher training error than the 18-layer oneConceptArchitectureMultiple choiceEasyPro
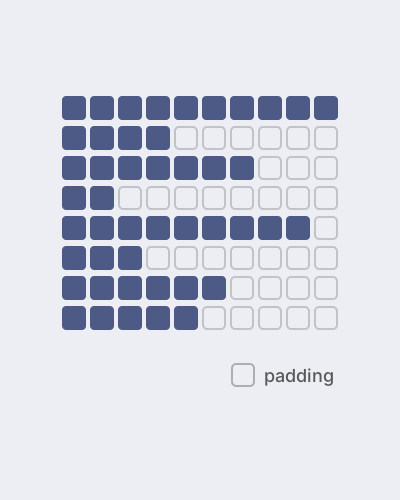 BatchNorm in a language model: eval loss depends on the batchConceptNormalizationMultiple choiceMediumPro
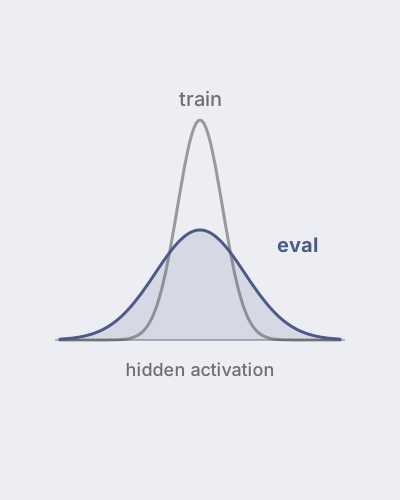 Dropout is off at inference and the activations come out twice as largeConceptRegularizationMultiple choiceEasyPro
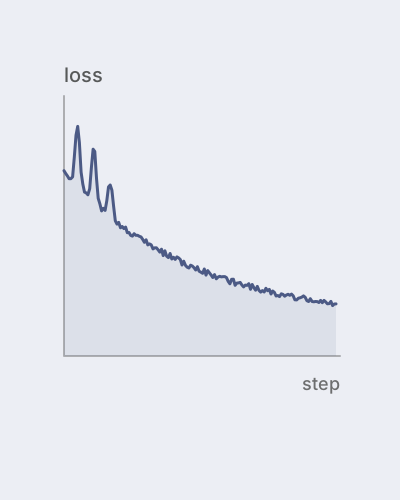 A hand-written Adam blows up in the first hundred stepsConceptOptimizationMultiple choiceEasyPro
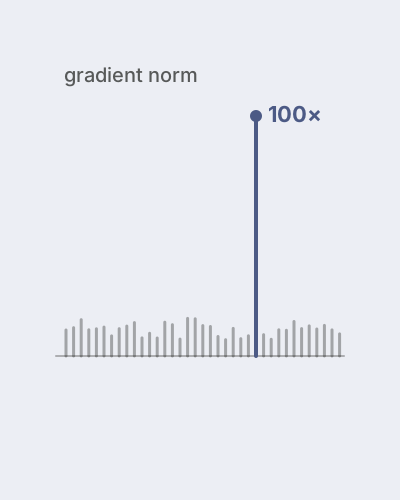 One batch in a few thousand blows the loss upConceptTraining stabilityMultiple choiceEasyPro
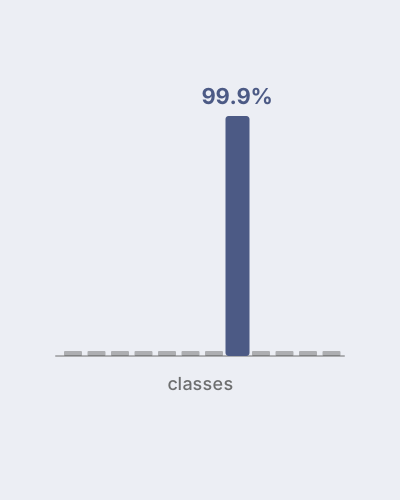 The top logit keeps pulling away from the restConceptRegularizationMultiple choiceEasyPro
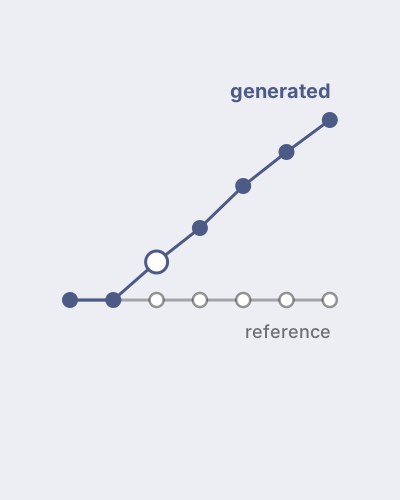 Teacher-forced loss looks great, but one wrong word derails the captionConceptOptimizationMultiple choiceMediumPro
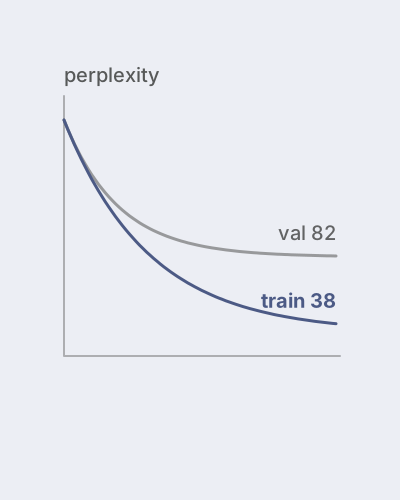 A word-level LSTM with 30M embedding parameters overfitsConceptArchitectureMultiple choiceEasyPro
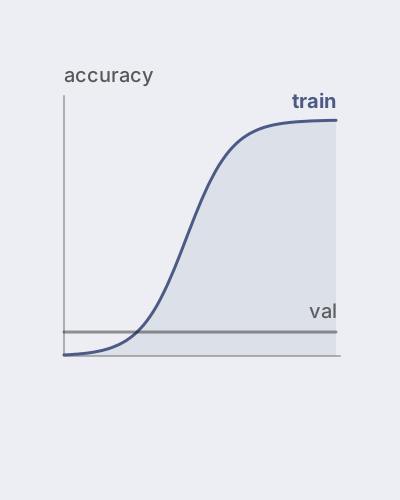 Training accuracy hits 100% while validation never leaves chanceConceptDataMultiple choiceMediumPro
 Choosing and checking the init for a deep ReLU netConceptInitializationShort answerMediumPro
 Writing a cross-entropy kernel that survives fp16 logitsConceptTraining stabilityShort answerHardPro
 Setting the gradient-clipping threshold for a new runConceptTraining stabilityShort answerMediumPro
 Explaining why a language model shouldn't use BatchNormConceptNormalizationShort answerMediumPro
 An L2 penalty under Adam barely shrinks the high-gradient weightsOptimizationMultiple choiceMediumPro
 Beam search loops, full sampling derails into the tailInferenceMultiple choiceMediumPro
 A Post-LN Transformer trains far worse without warmupMistral AITraining stabilityMultiple choiceMediumPro
 The right document is retrieved, but the model misses it in the middleLong contextMultiple choiceMediumPro
 The token budget grew mid-run, but the cosine already planned its decayScalingMultiple choiceMediumPro
 Batch 256 to 8,192 on 256 GPUs, and accuracy dropsOptimizationMultiple choiceMediumPro
 120 GB of identical optimizer state on every one of 64 GPUsDistributed trainingMultiple choiceMediumPro
 Raise the distillation temperature and the soft loss stops matteringDistillationMultiple choiceMediumPro
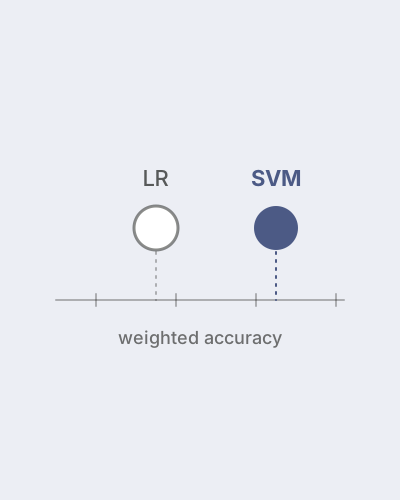 The SVM beats your logistic regression on the metric you shipConceptOptimizationMultiple choiceMediumPro
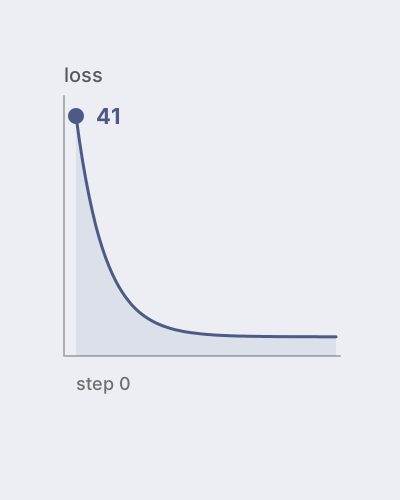 The loss is 41 before the first update on a 32K vocabularyConceptInitializationMultiple choiceEasyPro
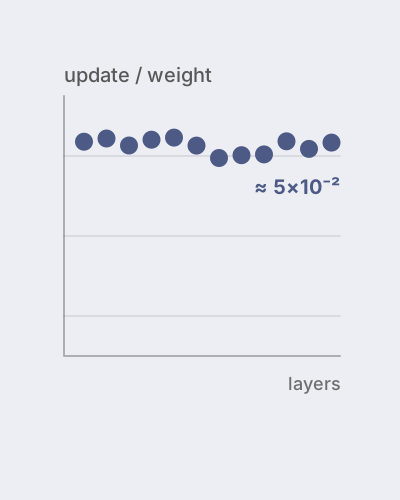 Every step rewrites 5% of each layer's weightsConceptOptimizationMultiple choiceMediumPro
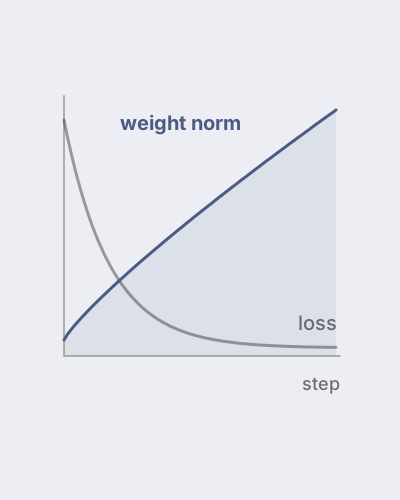 A linear probe whose weights never stop growingConceptRegularizationShort answerMediumPro
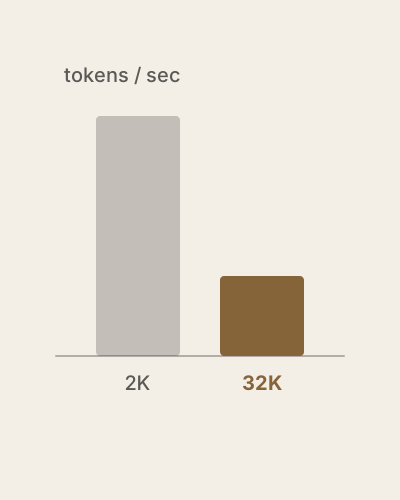 At 32K context, tokens per second fall to a thirdConceptScalingMultiple choiceMediumPro
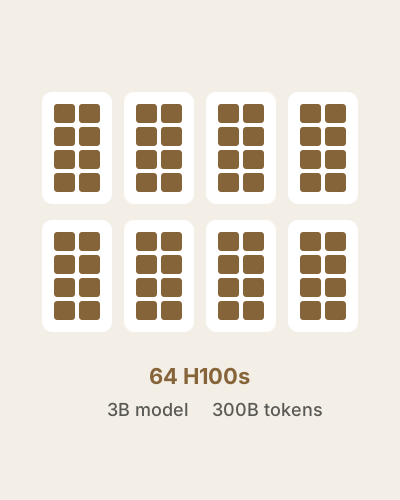 How long will 300B tokens take on 64 H100s?ConceptScalingMultiple choiceEasyPro
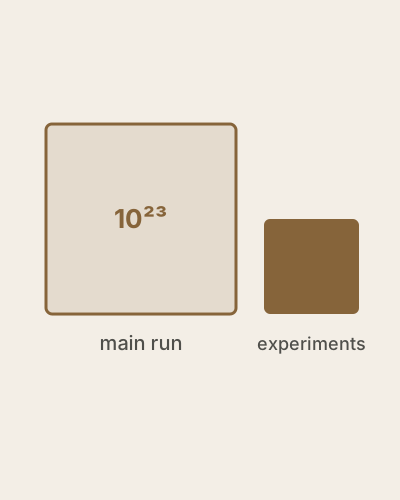 Picking the model size for a fixed compute budgetConceptScalingShort answerHardPro
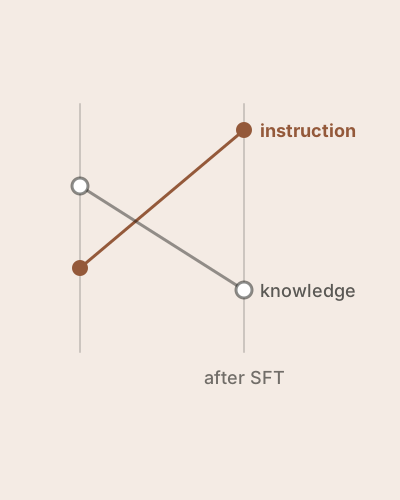 40B tokens of instruction data, and SFT on all of it costs knowledgeConceptDataMultiple choiceMediumPro
 Teaching a left-to-right code model to fill in the middleConceptDataShort answerHardPro
 The summarization SFT loss falls fast, and the summaries barely changeConceptFine-tuningMultiple choiceEasyPro
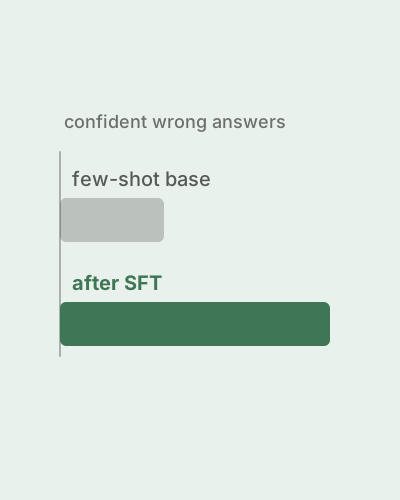 After SFT on expert answers, the model invents more specificsConceptFine-tuningMultiple choiceMediumPro
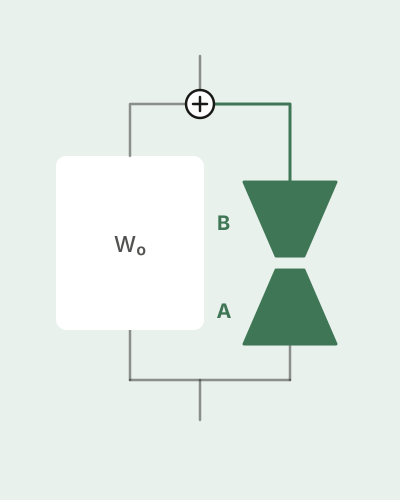 A single LoRA fine-tune decodes slower than its base modelConceptFine-tuningMultiple choiceEasyPro
 Choosing the KL strength for a DPO runConceptRLHFShort answerMediumPro
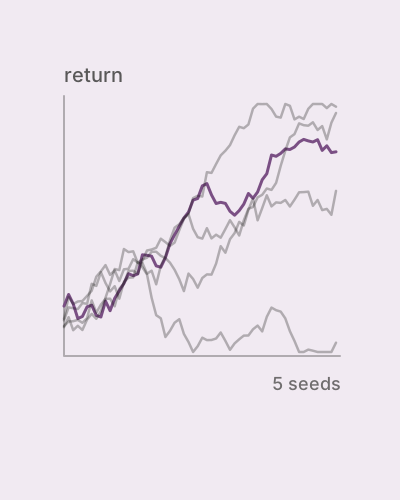 A PPO agent with a good critic still learns erraticallyConceptPolicy gradientsMultiple choiceMediumPro
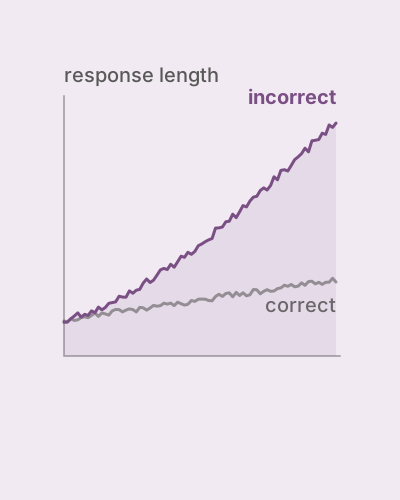 GRPO on math, and the wrong answers keep getting longerConceptRLVRMultiple choiceHardPro
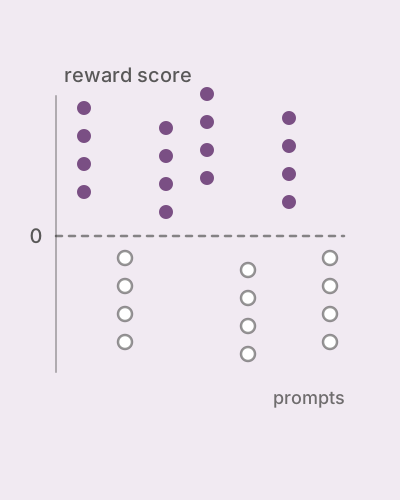 Filtering RL prompts with a reward-model thresholdConceptRLHFMultiple choiceMediumPro
 Checking the reward function before math RLConceptRLVRShort answerMediumPro
 Best-of-16 with a 6,000-token prompt, and prefill eats the budgetConceptInferenceMultiple choiceEasyPro
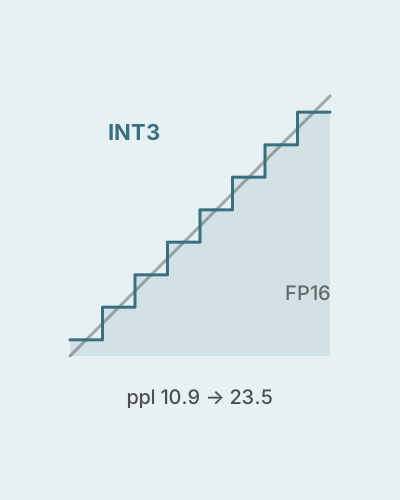 INT3 weights more than double the perplexityConceptQuantizationMultiple choiceHardPro
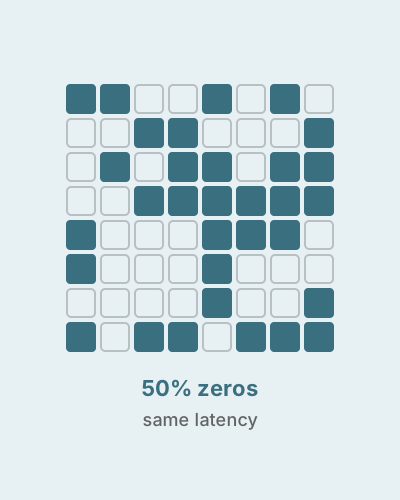 Half the weights pruned, and no speedupConceptInferenceShort answerMediumPro
 RL wins at pass@1 but the base model wins at pass@256RLVRMultiple choiceHardPro
 A small high-quality math set and the learning rate is about to decayMistral AIDataMultiple choiceMediumPro
 Twice the SFT data from the same source, and the answers are no betterFine-tuningMultiple choiceMediumPro
 A long prompt arrives and every running stream stallsServingMultiple choiceHardPro
 GRPO's samples go identical and accuracy stalls early in trainingRLVRMultiple choiceHardPro
 Loss near zero in an hour, but generation is gibberishAttentionMultiple choiceEasyPro
 Labelers prefer the RLHF model, but SQuAD and DROP scores fellRLHFMultiple choiceMediumPro
 Extending to 128K on mostly books, and short-text loss risesLong contextMultiple choiceMediumPro
